<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" xml:lang="ko"><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://scalefreeus.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://scalefreeus.github.io/" rel="alternate" type="text/html" hreflang="ko" /><updated>2024-12-19T10:40:26+09:00</updated><id>https://scalefreeus.github.io/feed.xml</id><title type="html">Scale Free Us</title><subtitle>Your Site Description
</subtitle><author><name>Your Name</name></author><entry><title type="html">데이터의 종류</title><link href="https://scalefreeus.github.io/2024/12/14/datatypes.html" rel="alternate" type="text/html" title="데이터의 종류" /><published>2024-12-14T00:00:00+09:00</published><updated>2024-12-14T00:00:00+09:00</updated><id>https://scalefreeus.github.io/2024/12/14/datatypes</id><content type="html" xml:base="https://scalefreeus.github.io/2024/12/14/datatypes.html"><![CDATA[<h1 id="데이터의-종류">데이터의 종류</h1>
<p>데이터 분석을 위해서는 먼저 데이터가 어떤 종류인지 파악하는 것이 중요하다. 왜냐하면 데이터의 종류에 따라 사용할 수 있는 분석 기법이 달라지기 때문이다.</p>

<h2 id="정형-데이터-structured-data">정형 데이터 (Structured Data)</h2>

<p>정형데이터의 분류</p>
<ol>
  <li>질적 데이터 (Qualitative Data)
품질, 특성 또는 특성의 유무를 나타내는 비수치적 데이터. 범주형 데이터라고도 불리며, 수학적 계산이 가능하더라도 의미는 없다.</li>
</ol>

<ul>
  <li>명목형 데이터(nominal data): 순서의 개념이 없다.</li>
  <li>서열형 데이터(ordinal data): 순서의 개념이 있다.</li>
</ul>

<ol>
  <li>양적 데이터 (Quantitative Data)
양이나 수치를 나태낼 수 있는 데이터로, 수학적 계산이 가능한 데이터.</li>
</ol>

<ul>
  <li>연속형 데이터 (Continuous Data): 실수와 같이 연속적인 수치를 나타내는 데이터</li>
  <li>이산형 데이터 (Discrete Data): 정수와 같이 불연속적인 수치를 나타내는 데이터.</li>
</ul>

<h2 id="비정형-데이터-unstructured-data">비정형 데이터 (Unstructured Data)</h2>

<p>텍스트나 음성, 비디오와 같이 구조가 없거나 제한적인 구조를 가지고 있지 않은 데이터</p>

<h2 id="반정형-데이터-semi-structed-data">반정형 데이터 (Semi-Structed Data)</h2>

<p>일정한 형식을 지니고 있지만 완전한 정형 데이터는 아닌 데이터</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">pandas</span> <span class="k">as</span> <span class="n">pd</span>
<span class="n">df</span> <span class="o">=</span> <span class="n">pd</span><span class="p">.</span><span class="n">read_csv</span><span class="p">(</span><span class="s">'data/titanic.csv'</span><span class="p">)</span>
<span class="n">df</span><span class="p">.</span><span class="n">head</span><span class="p">()</span>
</code></pre></div></div>

<div>
<style scoped="">
    .dataframe tbody tr th:only-of-type {
        vertical-align: middle;
    }

    .dataframe tbody tr th {
        vertical-align: top;
    }

    .dataframe thead th {
        text-align: right;
    }
</style>
<table border="1" class="dataframe">
  <thead>
    <tr style="text-align: right;">
      <th></th>
      <th>PassengerId</th>
      <th>Survived</th>
      <th>Pclass</th>
      <th>Name</th>
      <th>Sex</th>
      <th>Age</th>
      <th>SibSp</th>
      <th>Parch</th>
      <th>Ticket</th>
      <th>Fare</th>
      <th>Cabin</th>
      <th>Embarked</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <th>0</th>
      <td>1</td>
      <td>0</td>
      <td>3</td>
      <td>Braund, Mr. Owen Harris</td>
      <td>male</td>
      <td>22.0</td>
      <td>1</td>
      <td>0</td>
      <td>A/5 21171</td>
      <td>7.2500</td>
      <td>NaN</td>
      <td>S</td>
    </tr>
    <tr>
      <th>1</th>
      <td>2</td>
      <td>1</td>
      <td>1</td>
      <td>Cumings, Mrs. John Bradley (Florence Briggs Th...</td>
      <td>female</td>
      <td>38.0</td>
      <td>1</td>
      <td>0</td>
      <td>PC 17599</td>
      <td>71.2833</td>
      <td>C85</td>
      <td>C</td>
    </tr>
    <tr>
      <th>2</th>
      <td>3</td>
      <td>1</td>
      <td>3</td>
      <td>Heikkinen, Miss. Laina</td>
      <td>female</td>
      <td>26.0</td>
      <td>0</td>
      <td>0</td>
      <td>STON/O2. 3101282</td>
      <td>7.9250</td>
      <td>NaN</td>
      <td>S</td>
    </tr>
    <tr>
      <th>3</th>
      <td>4</td>
      <td>1</td>
      <td>1</td>
      <td>Futrelle, Mrs. Jacques Heath (Lily May Peel)</td>
      <td>female</td>
      <td>35.0</td>
      <td>1</td>
      <td>0</td>
      <td>113803</td>
      <td>53.1000</td>
      <td>C123</td>
      <td>S</td>
    </tr>
    <tr>
      <th>4</th>
      <td>5</td>
      <td>0</td>
      <td>3</td>
      <td>Allen, Mr. William Henry</td>
      <td>male</td>
      <td>35.0</td>
      <td>0</td>
      <td>0</td>
      <td>373450</td>
      <td>8.0500</td>
      <td>NaN</td>
      <td>S</td>
    </tr>
  </tbody>
</table>
</div>

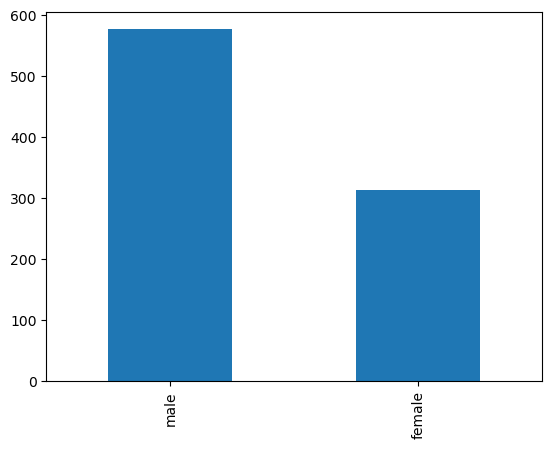
<p>여기서 성별(Sex)는 <code class="language-plaintext highlighter-rouge">male</code>, <code class="language-plaintext highlighter-rouge">female</code>값을 갖고 수학적 계산을 할 수 없고 순서의 개념도 없는 명목형 데이터이다.
보통의 경우 갯수를 세는  방식으로 분석을 한다.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">df</span><span class="p">[</span><span class="s">'Sex'</span><span class="p">].</span><span class="n">value_counts</span><span class="p">().</span><span class="n">plot</span><span class="p">.</span><span class="n">bar</span><span class="p">()</span>
</code></pre></div></div>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&lt;Axes: &gt;
</code></pre></div></div>

<p><img src="/assets/notebooks/2024-12-14-datatypes_files/2024-12-14-datatypes_4_1.png" alt="Jupyter Notebook Plot" /></p>

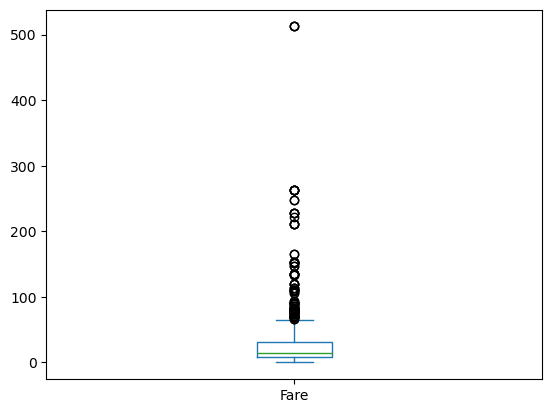
<p>요금(Fare)의 경우 실수 값을 갖고 수학적 계산이 가능하며 연속적인 수치값을 갖는 연속형 데이터이다. 평균과 같은 통계값 계산이 가능하다.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">df</span><span class="p">[</span><span class="s">'Fare'</span><span class="p">].</span><span class="n">plot</span><span class="p">.</span><span class="n">box</span><span class="p">()</span>
</code></pre></div></div>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&lt;Axes: &gt;
</code></pre></div></div>

<p><img src="/assets/notebooks/2024-12-14-datatypes_files/2024-12-14-datatypes_6_1.png" alt="Jupyter Notebook Plot" /></p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code>
</code></pre></div></div>]]></content><author><name>Your Name</name></author><category term="data" /><summary type="html"><![CDATA[데이터의 종류 데이터 분석을 위해서는 먼저 데이터가 어떤 종류인지 파악하는 것이 중요하다. 왜냐하면 데이터의 종류에 따라 사용할 수 있는 분석 기법이 달라지기 때문이다. 정형 데이터 (Structured Data) 정형데이터의 분류 질적 데이터 (Qualitative Data) 품질, 특성 또는 특성의 유무를 나타내는 비수치적 데이터. 범주형 데이터라고도 불리며, 수학적 계산이 가능하더라도 의미는 없다. 명목형 데이터(nominal data): 순서의 개념이 없다. 서열형 데이터(ordinal data): 순서의 개념이 있다. 양적 데이터 (Quantitative Data) 양이나 수치를 나태낼 수 있는 데이터로, 수학적 계산이 가능한 데이터. 연속형 데이터 (Continuous Data): 실수와 같이 연속적인 수치를 나타내는 데이터 이산형 데이터 (Discrete Data): 정수와 같이 불연속적인 수치를 나타내는 데이터. 비정형 데이터 (Unstructured Data) 텍스트나 음성, 비디오와 같이 구조가 없거나 제한적인 구조를 가지고 있지 않은 데이터 반정형 데이터 (Semi-Structed Data) 일정한 형식을 지니고 있지만 완전한 정형 데이터는 아닌 데이터 import pandas as pd df = pd.read_csv('data/titanic.csv') df.head() PassengerId Survived Pclass Name Sex Age SibSp Parch Ticket Fare Cabin Embarked 0 1 0 3 Braund, Mr. Owen Harris male 22.0 1 0 A/5 21171 7.2500 NaN S 1 2 1 1 Cumings, Mrs. John Bradley (Florence Briggs Th... female 38.0 1 0 PC 17599 71.2833 C85 C 2 3 1 3 Heikkinen, Miss. Laina female 26.0 0 0 STON/O2. 3101282 7.9250 NaN S 3 4 1 1 Futrelle, Mrs. Jacques Heath (Lily May Peel) female 35.0 1 0 113803 53.1000 C123 S 4 5 0 3 Allen, Mr. William Henry male 35.0 0 0 373450 8.0500 NaN S 여기서 성별(Sex)는 male, female값을 갖고 수학적 계산을 할 수 없고 순서의 개념도 없는 명목형 데이터이다. 보통의 경우 갯수를 세는 방식으로 분석을 한다. df['Sex'].value_counts().plot.bar() &lt;Axes: &gt; 요금(Fare)의 경우 실수 값을 갖고 수학적 계산이 가능하며 연속적인 수치값을 갖는 연속형 데이터이다. 평균과 같은 통계값 계산이 가능하다. df['Fare'].plot.box() &lt;Axes: &gt;]]></summary></entry><entry><title type="html">test jupyter notebook</title><link href="https://scalefreeus.github.io/2024/08/31/tests.html" rel="alternate" type="text/html" title="test jupyter notebook" /><published>2024-08-31T00:00:00+09:00</published><updated>2024-08-31T00:00:00+09:00</updated><id>https://scalefreeus.github.io/2024/08/31/tests</id><content type="html" xml:base="https://scalefreeus.github.io/2024/08/31/tests.html"><![CDATA[<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">numpy</span> <span class="k">as</span> <span class="n">np</span>
</code></pre></div></div>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">a</span> <span class="o">=</span> <span class="n">np</span><span class="p">.</span><span class="n">linspace</span><span class="p">(</span><span class="mi">0</span><span class="p">,</span> <span class="mi">10</span><span class="p">)</span>
<span class="n">a</span>
</code></pre></div></div>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>array([ 0.        ,  0.20408163,  0.40816327,  0.6122449 ,  0.81632653,
        1.02040816,  1.2244898 ,  1.42857143,  1.63265306,  1.83673469,
        2.04081633,  2.24489796,  2.44897959,  2.65306122,  2.85714286,
        3.06122449,  3.26530612,  3.46938776,  3.67346939,  3.87755102,
        4.08163265,  4.28571429,  4.48979592,  4.69387755,  4.89795918,
        5.10204082,  5.30612245,  5.51020408,  5.71428571,  5.91836735,
        6.12244898,  6.32653061,  6.53061224,  6.73469388,  6.93877551,
        7.14285714,  7.34693878,  7.55102041,  7.75510204,  7.95918367,
        8.16326531,  8.36734694,  8.57142857,  8.7755102 ,  8.97959184,
        9.18367347,  9.3877551 ,  9.59183673,  9.79591837, 10.        ])
</code></pre></div></div>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">a</span><span class="p">.</span><span class="nb">sum</span><span class="p">()</span>
</code></pre></div></div>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>250.0
</code></pre></div></div>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">b</span> <span class="o">=</span> <span class="n">np</span><span class="p">.</span><span class="n">linspace</span><span class="p">(</span><span class="mi">10</span><span class="p">,</span> <span class="mi">20</span><span class="p">)</span>
<span class="n">b</span>
</code></pre></div></div>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>array([10.        , 10.20408163, 10.40816327, 10.6122449 , 10.81632653,
       11.02040816, 11.2244898 , 11.42857143, 11.63265306, 11.83673469,
       12.04081633, 12.24489796, 12.44897959, 12.65306122, 12.85714286,
       13.06122449, 13.26530612, 13.46938776, 13.67346939, 13.87755102,
       14.08163265, 14.28571429, 14.48979592, 14.69387755, 14.89795918,
       15.10204082, 15.30612245, 15.51020408, 15.71428571, 15.91836735,
       16.12244898, 16.32653061, 16.53061224, 16.73469388, 16.93877551,
       17.14285714, 17.34693878, 17.55102041, 17.75510204, 17.95918367,
       18.16326531, 18.36734694, 18.57142857, 18.7755102 , 18.97959184,
       19.18367347, 19.3877551 , 19.59183673, 19.79591837, 20.        ])
</code></pre></div></div>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">a</span><span class="o">@</span><span class="n">b</span>
</code></pre></div></div>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>4183.673469387755
</code></pre></div></div>]]></content><author><name>Your Name</name></author><category term="math" /><summary type="html"><![CDATA[import numpy as np a = np.linspace(0, 10) a array([ 0. , 0.20408163, 0.40816327, 0.6122449 , 0.81632653, 1.02040816, 1.2244898 , 1.42857143, 1.63265306, 1.83673469, 2.04081633, 2.24489796, 2.44897959, 2.65306122, 2.85714286, 3.06122449, 3.26530612, 3.46938776, 3.67346939, 3.87755102, 4.08163265, 4.28571429, 4.48979592, 4.69387755, 4.89795918, 5.10204082, 5.30612245, 5.51020408, 5.71428571, 5.91836735, 6.12244898, 6.32653061, 6.53061224, 6.73469388, 6.93877551, 7.14285714, 7.34693878, 7.55102041, 7.75510204, 7.95918367, 8.16326531, 8.36734694, 8.57142857, 8.7755102 , 8.97959184, 9.18367347, 9.3877551 , 9.59183673, 9.79591837, 10. ]) a.sum() 250.0 b = np.linspace(10, 20) b array([10. , 10.20408163, 10.40816327, 10.6122449 , 10.81632653, 11.02040816, 11.2244898 , 11.42857143, 11.63265306, 11.83673469, 12.04081633, 12.24489796, 12.44897959, 12.65306122, 12.85714286, 13.06122449, 13.26530612, 13.46938776, 13.67346939, 13.87755102, 14.08163265, 14.28571429, 14.48979592, 14.69387755, 14.89795918, 15.10204082, 15.30612245, 15.51020408, 15.71428571, 15.91836735, 16.12244898, 16.32653061, 16.53061224, 16.73469388, 16.93877551, 17.14285714, 17.34693878, 17.55102041, 17.75510204, 17.95918367, 18.16326531, 18.36734694, 18.57142857, 18.7755102 , 18.97959184, 19.18367347, 19.3877551 , 19.59183673, 19.79591837, 20. ]) a@b 4183.673469387755]]></summary></entry><entry><title type="html">sample jupyter notebook</title><link href="https://scalefreeus.github.io/2023/10/05/sample.html" rel="alternate" type="text/html" title="sample jupyter notebook" /><published>2023-10-05T00:00:00+09:00</published><updated>2023-10-05T00:00:00+09:00</updated><id>https://scalefreeus.github.io/2023/10/05/sample</id><content type="html" xml:base="https://scalefreeus.github.io/2023/10/05/sample.html"><![CDATA[<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">matplotlib.pyplot</span> <span class="k">as</span> <span class="n">plt</span>
<span class="kn">import</span> <span class="nn">numpy</span> <span class="k">as</span> <span class="n">np</span>

<span class="o">%</span><span class="n">matplotlib</span> <span class="n">inline</span>
</code></pre></div></div>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">data</span> <span class="o">=</span> <span class="n">np</span><span class="p">.</span><span class="n">array</span><span class="p">([</span><span class="mi">1</span><span class="p">,</span> <span class="mi">2</span><span class="p">,</span> <span class="mi">3</span><span class="p">])</span>
</code></pre></div></div>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">plt</span><span class="p">.</span><span class="n">plot</span><span class="p">(</span><span class="n">data</span><span class="p">)</span>
</code></pre></div></div>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>[&lt;matplotlib.lines.Line2D at 0x7f3bd7089690&gt;]
</code></pre></div></div>

<p><img src="/assets/notebooks/2023-10-05-sample_files/2023-10-05-sample_3_1.png" alt="Jupyter Notebook Plot" /></p>]]></content><author><name>Your Name</name></author><category term="math" /><summary type="html"><![CDATA[import matplotlib.pyplot as plt import numpy as np %matplotlib inline data = np.array([1, 2, 3]) plt.plot(data) [&lt;matplotlib.lines.Line2D at 0x7f3bd7089690&gt;]]]></summary></entry><entry><title type="html">Terminology</title><link href="https://scalefreeus.github.io/2023/10/04/terminology.html" rel="alternate" type="text/html" title="Terminology" /><published>2023-10-04T00:00:00+09:00</published><updated>2023-10-04T00:00:00+09:00</updated><id>https://scalefreeus.github.io/2023/10/04/terminology</id><content type="html" xml:base="https://scalefreeus.github.io/2023/10/04/terminology.html"><![CDATA[<h1 id="기본-용어">기본 용어</h1>

<h2 id="변수의-타입">변수의 타입</h2>
<pre>
범주형 (categorical data)
    명목형 (nominal data)
        숫자로 바뀌어도 그 값이 크고 작음을 나타내는 것이 아니라 단순히 범주를 표시
    순서형 (ordinal data)
        값들 사이에 분명한 순위가 있음
        대부분 수치형 자료를 그룹화 하여 순서형 자료로 바꿈
수치형 (numerical data)
    이산형 (discrete data)
        셀 수 있는 형태의 자료
    연속형 (continuous data)
        등간형 (interval)
            비교할 수 있도록 단위가 정해진 경우 +, -만 가능
        비율형 (ratio)
            0이 없음을 의미하는 경우 (절대 0점), 사칙연산 가능
</pre>

<h2 id="통계-용어">통계 용어</h2>
<ul>
  <li>모집단 (population) : 통계분석 방법을 적용할 관심 대상의 전체 집합</li>
  <li>모수 (parameters) : 모집단을 분석하여 얻어지는 결과 수치</li>
  <li>표본 (sample): 직접적인 조사 대상이 된 모집단의 일부</li>
  <li>통계량 (statistics): 표본을 분석하여 얻어지는 결과 수치</li>
</ul>

<h2 id="가설검정-hypothesis-test">가설검정 (Hypothesis test)</h2>
<ul>
  <li>귀무가설 (null hypothesis, H0): 우연 때문이라는 가설 (유의어: 영가설)</li>
  <li>대립가설 (alternative hypothesis, H1): 귀무가설과의 대조 (증명하고자 하는 가설)</li>
  <li>일원검정 (one-way test) : 한 방향으로만 우연히 일어날 확률을 계산하는 가설검정</li>
  <li>이원검정 (two-way test) : 양방향으로 우연히 일어날 확률을 계산하는 가설검정</li>
</ul>

<h1 id="그리스-문자">그리스 문자</h1>

<table>
  <thead>
    <tr>
      <th>알파벳 대문자</th>
      <th>알파벳 소문자</th>
      <th>영어 표기법</th>
      <th>한글 표기법</th>
      <th>주의점</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>$\Huge A$</td>
      <td>$\Huge \alpha$</td>
      <td>alpha</td>
      <td>알파</td>
      <td>영어 a와 다르므로 주의</td>
    </tr>
    <tr>
      <td>$\Huge B$</td>
      <td>$\Huge \beta$</td>
      <td>beta</td>
      <td>베타</td>
      <td>영어 b와 다르므로 주의</td>
    </tr>
    <tr>
      <td>$\Huge \Gamma$</td>
      <td>$\Huge \gamma$</td>
      <td>gamma</td>
      <td>감마</td>
      <td>영어 r과 다르므로 주의</td>
    </tr>
    <tr>
      <td>$\Huge \Delta$</td>
      <td>$\Huge \delta$</td>
      <td>delta</td>
      <td>델타</td>
      <td> </td>
    </tr>
    <tr>
      <td>$\Huge E$</td>
      <td>$\Huge \epsilon$</td>
      <td>epsilon</td>
      <td>엡실론</td>
      <td>영어 e와 다르므로 주의</td>
    </tr>
    <tr>
      <td>$\Huge Z$</td>
      <td>$\Huge \zeta$</td>
      <td>zeta</td>
      <td>제타</td>
      <td> </td>
    </tr>
    <tr>
      <td>$\Huge H$</td>
      <td>$\Huge \eta$</td>
      <td>eta</td>
      <td>에타</td>
      <td> </td>
    </tr>
    <tr>
      <td>$\Huge \Theta$</td>
      <td>$\Huge \theta$</td>
      <td>theta</td>
      <td>쎄타</td>
      <td> </td>
    </tr>
    <tr>
      <td>$\Huge K$</td>
      <td>$\Huge \kappa$</td>
      <td>kappa</td>
      <td>카파</td>
      <td>영어 k와 다르므로 주의</td>
    </tr>
    <tr>
      <td>$\Huge \Lambda$</td>
      <td>$\Huge \lambda$</td>
      <td>lambda</td>
      <td>람다</td>
      <td> </td>
    </tr>
    <tr>
      <td>$\Huge M$</td>
      <td>$\Huge \mu$</td>
      <td>mu</td>
      <td>뮤</td>
      <td> </td>
    </tr>
    <tr>
      <td>$\Huge N$</td>
      <td>$\Huge \nu$</td>
      <td>nu</td>
      <td>누</td>
      <td>영어 v와 다르므로 주의</td>
    </tr>
    <tr>
      <td>$\Huge \Xi$</td>
      <td>$\Huge \xi$</td>
      <td>xi</td>
      <td>크싸이</td>
      <td> </td>
    </tr>
    <tr>
      <td>$\Huge \Pi$</td>
      <td>$\Huge \pi$</td>
      <td>pi</td>
      <td>파이</td>
      <td> </td>
    </tr>
    <tr>
      <td>$\Huge P$</td>
      <td>$\Huge \rho$</td>
      <td>rho</td>
      <td>로</td>
      <td>영어 p와 다르므로 주의</td>
    </tr>
    <tr>
      <td>$\Huge \Sigma$</td>
      <td>$\Huge \sigma$</td>
      <td>sigma</td>
      <td>시그마</td>
      <td>숫자 6과 다르므로 주의</td>
    </tr>
    <tr>
      <td>$\Huge T$</td>
      <td>$\Huge \tau$</td>
      <td>tau</td>
      <td>타우</td>
      <td>영어 t와 다르므로 주의</td>
    </tr>
    <tr>
      <td>$\Huge \Phi$</td>
      <td>$\Huge \phi$</td>
      <td>phi</td>
      <td>파이/피</td>
      <td> </td>
    </tr>
    <tr>
      <td>$\Huge X$</td>
      <td>$\Huge \chi$</td>
      <td>chi</td>
      <td>카이</td>
      <td>영어 x와 다르므로 주의</td>
    </tr>
    <tr>
      <td>$\Huge \Psi$</td>
      <td>$\Huge \psi$</td>
      <td>psi</td>
      <td>프사이</td>
      <td> </td>
    </tr>
    <tr>
      <td>$\Huge \Omega$</td>
      <td>$\Huge \omega$</td>
      <td>omega</td>
      <td>오메가</td>
      <td>영어 w와 다르므로 주의</td>
    </tr>
  </tbody>
</table>]]></content><author><name>Your Name</name></author><category term="Data Science" /><summary type="html"><![CDATA[기본 용어 변수의 타입 범주형 (categorical data) 명목형 (nominal data) 숫자로 바뀌어도 그 값이 크고 작음을 나타내는 것이 아니라 단순히 범주를 표시 순서형 (ordinal data) 값들 사이에 분명한 순위가 있음 대부분 수치형 자료를 그룹화 하여 순서형 자료로 바꿈 수치형 (numerical data) 이산형 (discrete data) 셀 수 있는 형태의 자료 연속형 (continuous data) 등간형 (interval) 비교할 수 있도록 단위가 정해진 경우 +, -만 가능 비율형 (ratio) 0이 없음을 의미하는 경우 (절대 0점), 사칙연산 가능 통계 용어 모집단 (population) : 통계분석 방법을 적용할 관심 대상의 전체 집합 모수 (parameters) : 모집단을 분석하여 얻어지는 결과 수치 표본 (sample): 직접적인 조사 대상이 된 모집단의 일부 통계량 (statistics): 표본을 분석하여 얻어지는 결과 수치 가설검정 (Hypothesis test) 귀무가설 (null hypothesis, H0): 우연 때문이라는 가설 (유의어: 영가설) 대립가설 (alternative hypothesis, H1): 귀무가설과의 대조 (증명하고자 하는 가설) 일원검정 (one-way test) : 한 방향으로만 우연히 일어날 확률을 계산하는 가설검정 이원검정 (two-way test) : 양방향으로 우연히 일어날 확률을 계산하는 가설검정 그리스 문자 알파벳 대문자 알파벳 소문자 영어 표기법 한글 표기법 주의점 $\Huge A$ $\Huge \alpha$ alpha 알파 영어 a와 다르므로 주의 $\Huge B$ $\Huge \beta$ beta 베타 영어 b와 다르므로 주의 $\Huge \Gamma$ $\Huge \gamma$ gamma 감마 영어 r과 다르므로 주의 $\Huge \Delta$ $\Huge \delta$ delta 델타   $\Huge E$ $\Huge \epsilon$ epsilon 엡실론 영어 e와 다르므로 주의 $\Huge Z$ $\Huge \zeta$ zeta 제타   $\Huge H$ $\Huge \eta$ eta 에타   $\Huge \Theta$ $\Huge \theta$ theta 쎄타   $\Huge K$ $\Huge \kappa$ kappa 카파 영어 k와 다르므로 주의 $\Huge \Lambda$ $\Huge \lambda$ lambda 람다   $\Huge M$ $\Huge \mu$ mu 뮤   $\Huge N$ $\Huge \nu$ nu 누 영어 v와 다르므로 주의 $\Huge \Xi$ $\Huge \xi$ xi 크싸이   $\Huge \Pi$ $\Huge \pi$ pi 파이   $\Huge P$ $\Huge \rho$ rho 로 영어 p와 다르므로 주의 $\Huge \Sigma$ $\Huge \sigma$ sigma 시그마 숫자 6과 다르므로 주의 $\Huge T$ $\Huge \tau$ tau 타우 영어 t와 다르므로 주의 $\Huge \Phi$ $\Huge \phi$ phi 파이/피   $\Huge X$ $\Huge \chi$ chi 카이 영어 x와 다르므로 주의 $\Huge \Psi$ $\Huge \psi$ psi 프사이   $\Huge \Omega$ $\Huge \omega$ omega 오메가 영어 w와 다르므로 주의]]></summary></entry><entry><title type="html">Links</title><link href="https://scalefreeus.github.io/2023/10/03/links.html" rel="alternate" type="text/html" title="Links" /><published>2023-10-03T00:00:00+09:00</published><updated>2023-10-03T00:00:00+09:00</updated><id>https://scalefreeus.github.io/2023/10/03/links</id><content type="html" xml:base="https://scalefreeus.github.io/2023/10/03/links.html"><![CDATA[<p><a href="https://m.blog.naver.com/luexr/222194967834">로그증명</a></p>

<p><a href="https://mpewsey.github.io/2021/12/05/converting-jupyter-notebooks-to-github-pages-posts.html">How to Use Jupyter Notebook for Github Pages Posts</a></p>]]></content><author><name>Your Name</name></author><category term="TeXt" /><summary type="html"><![CDATA[로그증명 How to Use Jupyter Notebook for Github Pages Posts]]></summary></entry><entry><title type="html">Welcome</title><link href="https://scalefreeus.github.io/2018/07/01/welcome.html" rel="alternate" type="text/html" title="Welcome" /><published>2018-07-01T00:00:00+09:00</published><updated>2018-07-01T00:00:00+09:00</updated><id>https://scalefreeus.github.io/2018/07/01/welcome</id><content type="html" xml:base="https://scalefreeus.github.io/2018/07/01/welcome.html"><![CDATA[<p>If you see this page, that means you have setup your site. enjoy! :ghost: :ghost: :ghost:</p>

<p>You may want to <a href="https://kitian616.github.io/jekyll-TeXt-theme/docs/en/configuration">config the site</a> or <a href="https://kitian616.github.io/jekyll-TeXt-theme/docs/en/writing-posts">writing a post</a> next. Please feel free to <a href="https://github.com/kitian616/jekyll-TeXt-theme/issues">create an issue</a> or <a href="mailto:kitian616@outlook.com">send me email</a> if you have any questions.</p>

<!--more-->

<hr />

<p>If you like TeXt, don’t forget to give me a star. :star2:</p>

<p><a href="https://github.com/kitian616/jekyll-TeXt-theme/"><img src="https://img.shields.io/github/stars/kitian616/jekyll-TeXt-theme.svg?label=Stars&amp;style=social" alt="Star This Project" /></a></p>]]></content><author><name>Your Name</name></author><category term="TeXt" /><summary type="html"><![CDATA[If you see this page, that means you have setup your site. enjoy! :ghost: :ghost: :ghost: You may want to config the site or writing a post next. Please feel free to create an issue or send me email if you have any questions.]]></summary></entry><entry><title type="html">Post with Header Image</title><link href="https://scalefreeus.github.io/2018/06/01/header-image.html" rel="alternate" type="text/html" title="Post with Header Image" /><published>2018-06-01T00:00:00+09:00</published><updated>2018-06-01T00:00:00+09:00</updated><id>https://scalefreeus.github.io/2018/06/01/header-image</id><content type="html" xml:base="https://scalefreeus.github.io/2018/06/01/header-image.html"><![CDATA[<p>A Post with Header Image, See <a href="https://kitian616.github.io/jekyll-TeXt-theme/samples.html#page-layout">Page layout</a> for more examples.</p>

<!--more-->]]></content><author><name>Your Name</name></author><category term="TeXt" /><summary type="html"><![CDATA[A Post with Header Image, See Page layout for more examples.]]></summary></entry></feed>